Architecture · 8 min read
AWS High Availability Architecture: What Businesses Should Consider
High availability is a business decision expressed through technical failure boundaries.
Fundamentals and why this matters
High availability is the ability to continue a defined service when expected failures occur. It is not a single AWS feature. Availability Zones provide independent failure boundaries within a Region, while Regions provide a larger isolation boundary at more operational cost. The architecture should begin with the business journeys that need continuity, their recovery objectives, and the dependencies that can prevent that continuity.
Architecture and important components
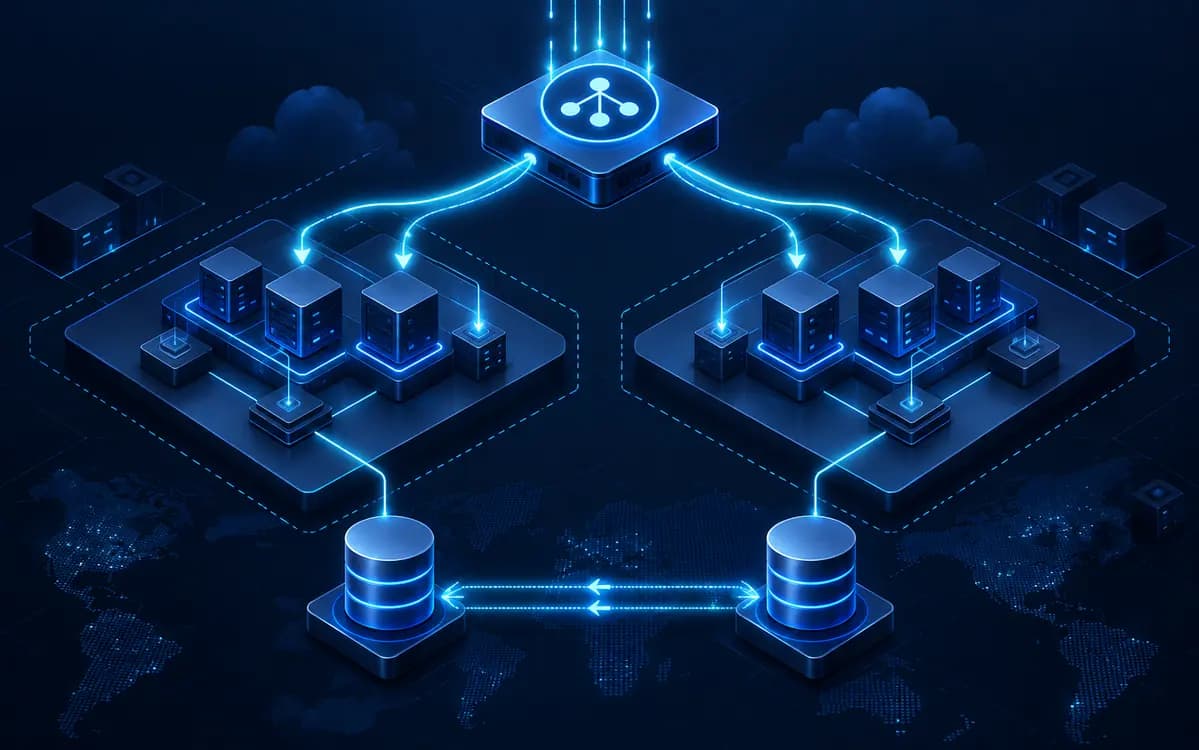
A common highly available web path is Route 53 health-aware DNS to an Application Load Balancer, then stateless EC2, ECS, or EKS application replicas distributed across at least two Availability Zones. Application state moves to managed data services: RDS Multi-AZ or Aurora for relational workloads, ElastiCache where cache loss is acceptable, S3 for durable objects, and queues for asynchronous work. Auto Scaling or workload autoscaling replaces failed capacity. Health checks must reflect readiness to serve, not merely a process listening on a port.
Production implementation guidance
Deploy multiple application replicas across zones, avoid single-instance sessions by using signed tokens or a shared session store, and separate static assets from compute. Configure ALB target health checks, connection draining, timeouts, and sensible autoscaling signals. RDS Multi-AZ addresses database instance availability but not every data or query problem; test application reconnect behavior and failover time. Backups, point-in-time recovery, and restore validation remain necessary even when a service is Multi-AZ.
Security and change-control considerations
High availability should not duplicate uncontrolled access. Keep workloads in private subnets, scope security groups by traffic intent, protect secrets in managed stores, encrypt data in transit and at rest, and ensure break-glass processes are audited. Cross-zone or multi-region replication changes data residency and key-management considerations. A resilient identity path matters too: deployment and monitoring access should not depend on one fragile credential or host.
Performance, monitoring, and operational considerations
Test the failure modes your architecture claims to handle: unhealthy application target, AZ capacity loss, database failover, unavailable cache, bad deployment, dependency timeout, and accidental deletion. Measure RTO and RPO from exercises, not diagrams. Monitor ALB target health, application errors, saturation, database replication and failover signals, queue depth, and user-visible latency. Decide which alarms trigger automated replacement and which require human assessment.
Production delivery and verification
Before changing a live $aws high availability architecture: what businesses should consider design, record the current baseline: ownership, dependency map, service objective, capacity or policy limit, and the signals that would prove the change helped. A change without a baseline is difficult to validate and easy to misattribute after the next deployment or traffic shift.
Make the smallest reversible change first. Test it in a representative non-production environment, then release with a bounded blast radius, a named owner, and a rollback condition. Change windows are not a substitute for safety; the practical controls are an identified previous state, compatible data or configuration, and a clear decision point for stopping the rollout.
During and after release, correlate infrastructure signals with the user journey. Watch error rate, latency, saturation, availability, and the workload-specific signal that prompted the work. Record the observed outcome in the engineering decision log. This turns a one-off fix into operational knowledge that can be reused during planning, incident response, and the next review.
Finally, keep the runbook current. It should state what normal looks like, what breaks first, who owns the dependency, how to collect evidence, and which action is safe under pressure. Good documentation is concise enough to use during an incident and specific enough to prevent an unsafe guess.
Decision guidance
Multi-AZ is usually the starting point for production services; multi-region is justified by explicit availability, latency, regulatory, or disaster objectives. Every added region introduces data replication, deployment, observability, and failback complexity. Choose the smallest architecture that meets documented failure tolerance, then practice it.
Related technical reading: AWS Disaster Recovery Strategies: From Backup to Multi-Site · Cloud Monitoring Strategy: Metrics, Logs, Traces and Alerting
Practical implementation checklist
- Distribute stateless application capacity across Availability Zones.
- Use managed data availability and tested backup/restore paths.
- Handle sessions, retries, and connection failover explicitly.
- Test failure scenarios and record measured RTO/RPO.
- Monitor user-facing health as well as infrastructure state.
Frequently asked questions
Is Multi-AZ the same as disaster recovery?
No. Multi-AZ addresses many in-region failures. Disaster recovery considers restore, regional loss, data corruption, and documented recovery operations.
Does an ALB make an application highly available?
Only if healthy application capacity, dependencies, data services, and network paths are also resilient.
When is multi-region worth it?
When measured business requirements justify its extra cost and operational complexity, and the organization can test failover and failback.